- marcusta2026-08-16
github.com
GitHub - xiaobright/dsh-anchored-standard: Two-phase DeepSeek Harness preset: Minimal-aligned...
Two-phase DeepSeek Harness preset: Minimal-aligned bootstrap, then full Standard tools (Project2 98/99)
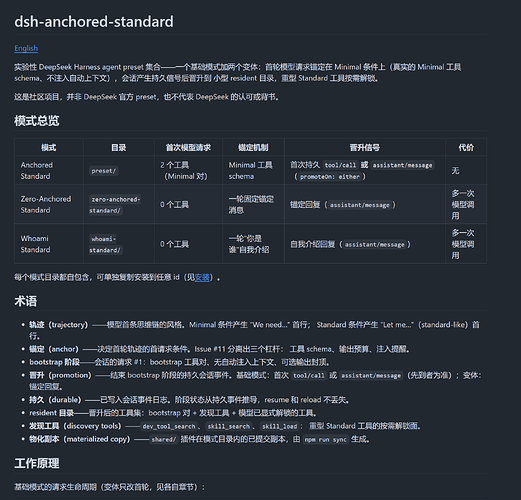
原理:首轮模拟极简预设,后续注入工具正常跑
使用感受:这个能让pro稳定一些,flash没试。实际使用中项目里有类似agents.md文件的,注入后还是会跑到 下面那个作者说的 spec 雷霆大思考路由。反正就是pro的第一轮对话要干净,不能哐哐哐注入一堆上下文,即便是浪费一轮对话,我看作者甚至搞了个第一轮直接发 who am I 对话的预设。
github.com
GitHub - yjh051108/dsh-router-standard: Task-aware reasoning-mode router for DeepSeek...
Task-aware reasoning-mode router for DeepSeek Harness: three measured behavior bands (spec/mixed/react) with phase-transition evidence, persona + first-turn tool injection, agent-visible tuning. Dual-attractor policy paper included.
原理:在原生深度路径和后压未收敛的极简路径找到断层,把断层当路由,实现了 “Let me / We need” 自路由
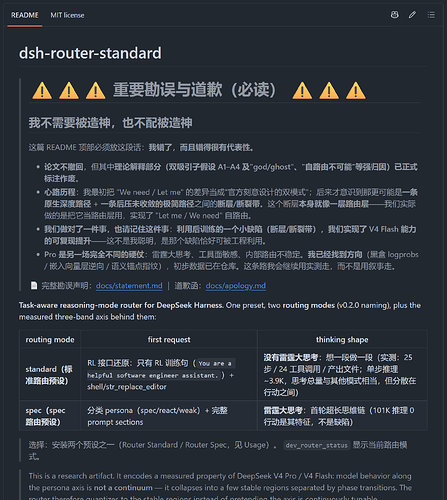
使用感受:这个应该是明确对flash提升比较大,看B友的反馈 flash一轮都给干出了黑洞模拟。
都是使用preset,感兴趣的自己去看看,用过反馈下使用感受。注意预设是在创建空白会话就加了,后续是改不了的。装了预设要用空白新会话
主楼 - LingEasy2026-08-16
我一直在奇怪。既然明显不同路由智商差距这么大。为何还保留那部分路由呢
- Merit2026-08-16
因为是同一个模型的不同能力的展现,就像你身体里有一个学霸的人格 当它需要激活才能出现 ^-^